Key Findings
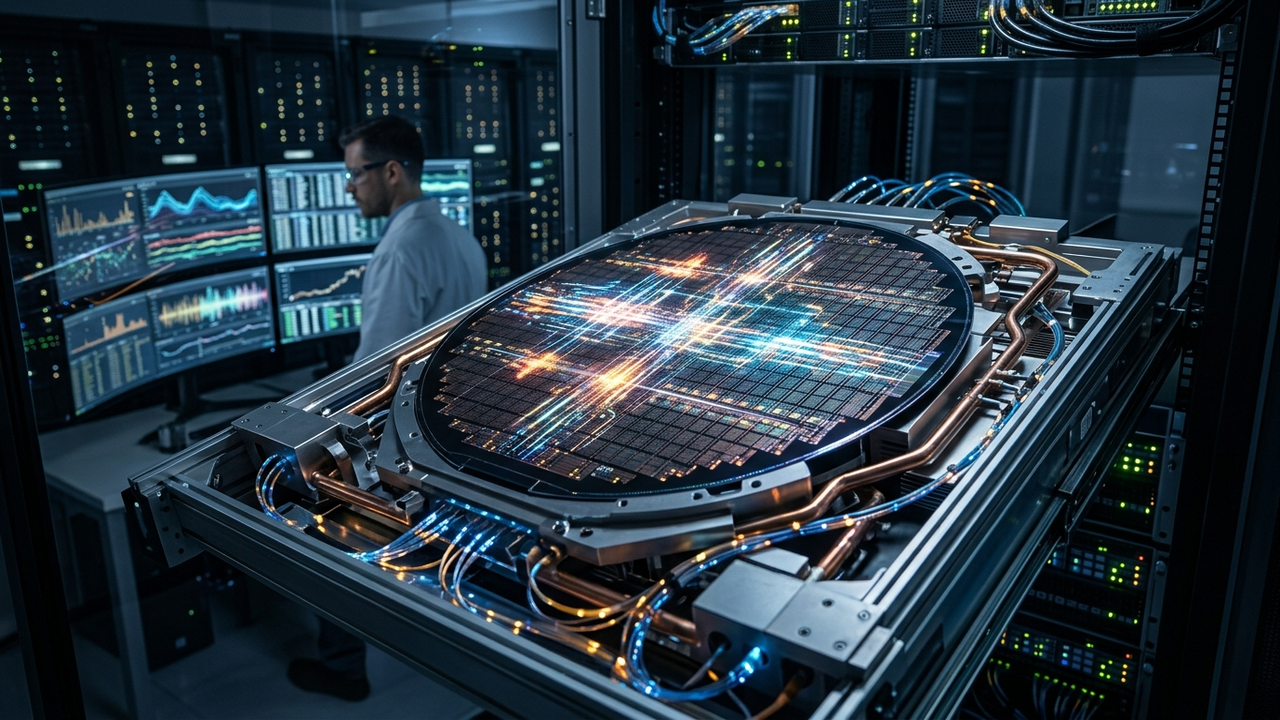
Cerebras Systems has unveiled the Wafer-Scale Engine 3 (WSE-3), demonstrating a groundbreaking advancement in AI inference capabilities. The WSE-3 delivers unprecedented ultra-low latency and exceptionally high throughput for large-scale generative AI models. This technology significantly expands the potential for real-time AI applications, including personalized content generation and complex drug discovery simulations.
Technical / Clinical Details
- The WSE-3 processor is built upon Cerebras’ unique wafer-scale technology, integrating trillions of transistors onto a single silicon wafer. This approach fundamentally eliminates the latency and bottlenecks typically associated with data transfer between multiple discrete chips.
- The elimination of memory bottlenecks is a crucial factor in dramatically accelerating inference speeds, particularly for very large AI models. By situating the entire model on a single processor, WSE-3 minimizes external memory accesses, reducing both energy consumption and time associated with data movement.
- As a result, the WSE-3 achieves unparalleled low-latency responses and high throughput, capable of simultaneously processing a massive volume of requests for current state-of-the-art generative AI models (e.g., those with billions to trillions of parameters). This provides a decisive advantage in diverse applications such as real-time conversational AI, instantaneous image and video generation, and advanced scientific simulations.
Background & Context
As AI rapidly evolves, the computational requirements for the inference phase of large language models and generative AI models are continuously escalating. These models demand both real-time responsiveness to users and the ability to process a high volume of requests concurrently, making the simultaneous achievement of low latency and high throughput essential. Traditional GPU architectures often encounter communication overhead bottlenecks when coordinating multiple GPUs, making Cerebras’ wafer-scale approach a notable solution to this fundamental challenge.
Strategic Significance & Outlook
The AI inference breakthrough enabled by WSE-3 opens new horizons, particularly within enterprise AI and high-performance computing. It will accelerate the adoption of real-time AI in areas such as real-time market analysis in financial services, instant diagnostic support in healthcare, and design optimization simulations in manufacturing. This technology is poised to foster the creation of new AI-driven services and products, promising transformative impacts across numerous industries globally.
Source: #
Get our weekly technology intelligence — free
Receive an infographic that lets you judge at a glance whether each field’s analysis report is worth reading.
Subscribe Free — Weekly Tech Intelligence
By subscribing, you’ll receive Troy-Technical’s weekly technology intelligence newsletter.
- Your email and selected fields are used only to deliver the newsletter.
- We never share your information with third parties.
- You can unsubscribe anytime via the link in each email.
See our Privacy Policy for details.
Takes about a minute · Unsubscribe anytime

Comments