Key Findings
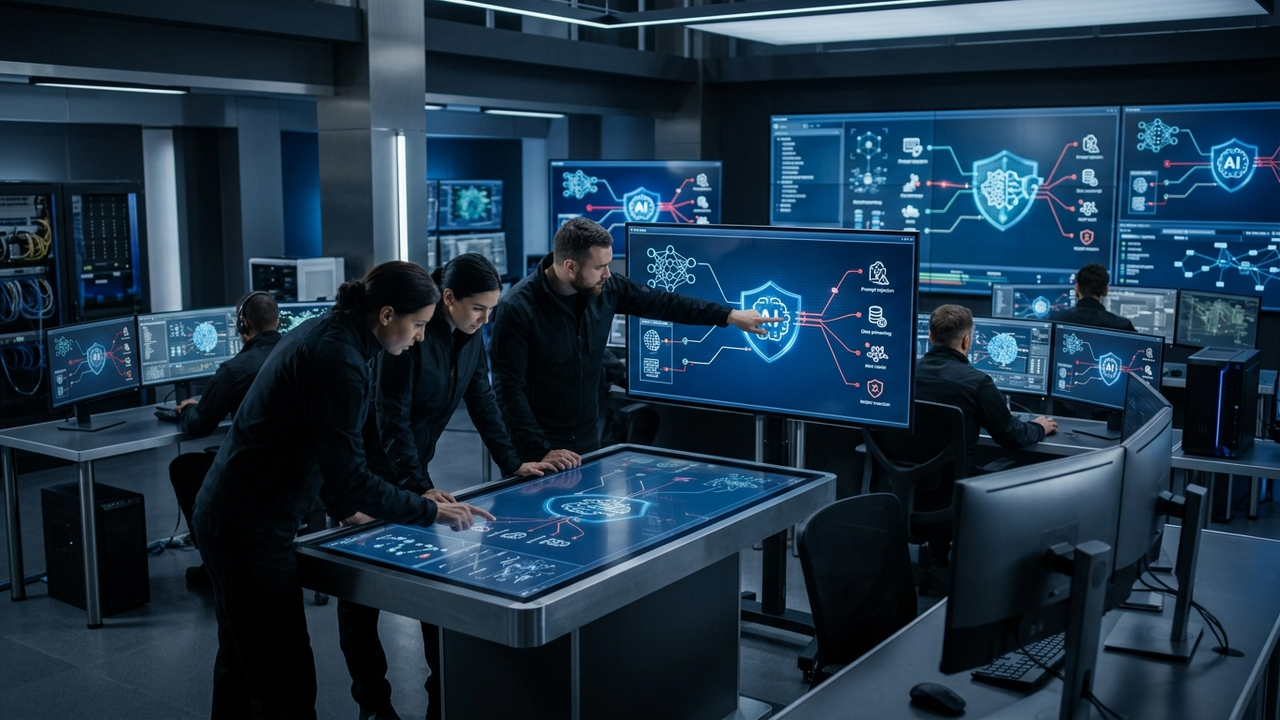
With the rapid advancement of AI technology, structured evaluation methods known as “AI Red Teaming” are becoming an urgent necessity across industries to ensure AI system safety and security. Frameworks such as MITRE ATLAS and OWASP Top 10 for LLMs are emerging as new standards for classifying AI-specific attack surfaces and identifying vulnerabilities.
Technical Details
AI Red Teaming aims to proactively identify and mitigate risks that could be caused by malicious actors or unforeseen system malfunctions. This process involves systematically analyzing the AI system’s functions, data, and interaction points to discover potential attack vectors and safety flaws:
- MITRE ATLAS (Adversarial Threat Landscape for Artificial-Intelligence Systems): A knowledge base that categorizes known attack techniques and tactics against AI systems. Adversaries can manipulate AI model training data, inference processes, or outputs to induce unintended system behaviors.
- OWASP Top 10 for Large Language Models (LLMs): Identifies and ranks the most common security risks specific to large language models. These include prompt injection, sensitive data leakage, training data poisoning, and improper tool use by AI agents.
Crucially, automated scanning tools alone are insufficient. Manual evaluations testing the entire “agent loop”—where an AI model reads documents, calls external tools, and integrates results back into its context—are indispensable. This approach allows for a deeper understanding of how AI systems behave in complex scenarios and more accurately identifies potential real-world adverse effects.
Background & Context
As AI becomes deeply integrated into critical societal infrastructures such as healthcare, finance, and public services, concerns about the safety and reliability of AI systems are escalating. Malfunctions or misuse of AI can lead to privacy breaches, discrimination, financial losses, and even threats to human life. The introduction of regulations like the EU AI Act further accelerates the drive for AI safety, placing a responsibility on companies to develop ethical and robust AI systems while ensuring compliance. AI Red Teaming is positioned as a critical security practice within the AI development lifecycle in this evolving landscape.
Strategic Significance & Outlook
The AI Red Teaming approach is expected to see further standardization and widespread adoption as AI technology matures. Beyond the evolution of frameworks and tools, a comprehensive approach integrating AI ethics, governance, and risk management (AI GRC) will become increasingly necessary. Companies that build in-house AI Red Teaming expertise or collaborate with external specialists will be able to minimize risks associated with AI system deployment, thereby safely and responsibly maximizing AI’s potential.
Source: https://dev.to/cgivre/ai-red-teaming-in-2026-the-frameworks-and-tools-that-matter-75j
Get our weekly technology intelligence — free
Receive an infographic that lets you judge at a glance whether each field’s analysis report is worth reading.
Subscribe Free — Weekly Tech Intelligence
By subscribing, you’ll receive Troy-Technical’s weekly technology intelligence newsletter.
- Your email and selected fields are used only to deliver the newsletter.
- We never share your information with third parties.
- You can unsubscribe anytime via the link in each email.
See our Privacy Policy for details.
Takes about a minute · Unsubscribe anytime

Comments