Key Findings
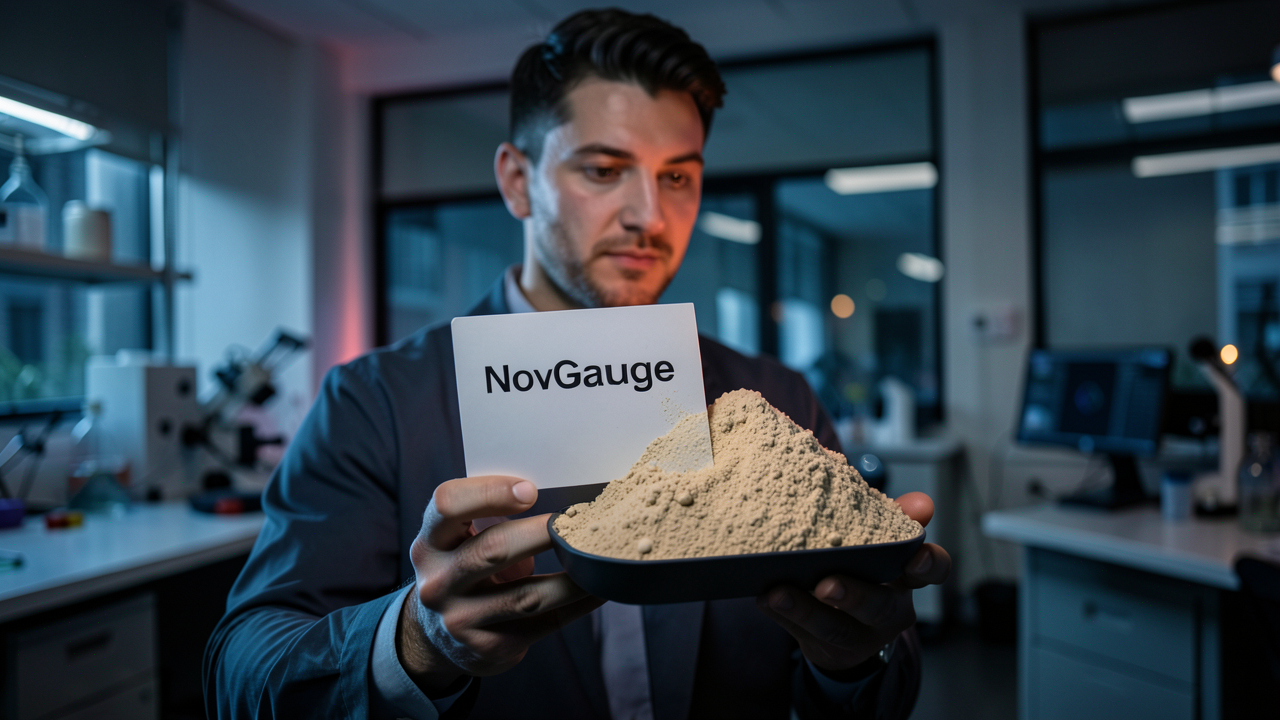
A new human-anchored, fine-grained benchmark called NovGauge has been introduced to rigorously diagnose the capability of Large Language Models (LLMs) in assessing the novelty of scientific papers. Evaluations using NovGauge on 18 prominent LLMs revealed a consistent tendency for models to generate hallucinations and provide novelty assessments lacking sufficient justification. This critical finding suggests that current LLMs are not yet reliable for complex scientific tasks such as evaluating research novelty, highlighting a significant gap in their scientific reasoning abilities.
Technical Details
- **Benchmark Design**: NovGauge consists of 619 pairs of scientific papers and 50 multi-paper sets, each meticulously annotated by human experts for novelty. This design allows for a nuanced comparison between LLM outputs and expert judgments, focusing on specific aspects of novelty.
- **Data Curation**: The dataset for NovGauge is derived from high-quality, expert-driven sources, including disagreements among reviewers at the International Conference on Learning Representations (ICLR) and co-citation networks of research papers. These sources capture the intricate and often subjective nature of novelty assessment within the scientific community.
- **Evaluated Models**: The benchmark was applied to 18 state-of-the-art LLMs, encompassing models from various developers, including different versions of GPT and Claude, as well as other leading open-source and proprietary models.
- **Diagnostic Insights**: The evaluations demonstrated that LLMs frequently mischaracterize the novelty of papers, sometimes claiming known ideas as novel or dismissing genuinely novel contributions. Crucially, the explanations provided by LLMs for their novelty judgments often lacked specific factual grounding, veering into ‘hallucinations’ or generic statements.
Background & Context
While LLMs have shown impressive capabilities in tasks like information retrieval, summarization, and text generation, their reliability in complex scientific domains, particularly those requiring deep expert knowledge such as assessing the novelty of academic research, remains underexplored. Novelty assessment is a cornerstone of scientific progress, influencing research direction, funding decisions, and publication outcomes. The inability of LLMs to perform this task reliably poses a significant barrier to their broader integration into scientific decision-making processes.
Strategic Significance & Outlook
The introduction of NovGauge is crucial for identifying the current limitations of LLMs in scientific reasoning, particularly concerning novelty assessment. This benchmark will serve as a vital tool to guide the development of more reliable and evidence-based LLMs. For LLMs to become truly valuable assistants to researchers and accelerate scientific discovery, it is imperative to address issues of hallucination, enhance their ability to generate grounded justifications, and improve their integration of sophisticated domain-specific knowledge. NovGauge provides a clear roadmap for these critical advancements.
Source: https://arxiv.org/html/2609.11234v1
Get our weekly technology intelligence — free
Receive an infographic that lets you judge at a glance whether each field’s analysis report is worth reading.
Subscribe Free — Weekly Tech Intelligence
By subscribing, you’ll receive Troy-Technical’s weekly technology intelligence newsletter.
- Your email and selected fields are used only to deliver the newsletter.
- We never share your information with third parties.
- You can unsubscribe anytime via the link in each email.
See our Privacy Policy for details.
Takes about a minute · Unsubscribe anytime

Comments