Latency– tag –
-

New LLM Inference Algorithm for Compute-in-Flash Systems Achieves 15x KV Cache Traffic Reduction, Delivering Energy and Latency Savings for Llama-3.1-8B and Qwen-2.5-7B
arXiv Unknown Overview Research published on arXiv introduces a novel algorithm enabling LLM inference on Compute-in-Flash systems, mitigating memory bandwidth limitations. This method employs end-to-end integer-only quantization and a d... -
LLM Test-Time Scaling: Candidate Generation Strategy Dramatically Increases Energy Consumption by 4.86x and Latency by 6.12x on A100 GPUs for Phi-3-mini and Qwen2.5-1.5B
Mobina Kashaniyan (referencing IEEE/ACM SC26 Workshop) Unknown Overview New research reveals that for LLM test-time scaling, the candidate generation strategy, not just the candidate count, critically impacts energy and performance. Eval... -
Samsung Research Unveils AnySimLite: Sub-700KB, Sub-30ms On-Device AI Matching 7B-Parameter LLMs for Speech Classification
Samsung Research South Korea Overview Samsung Research has introduced AnySimLite, a lightweight few-shot similarity encoder capable of delivering state-of-the-art performance for multiple on-device speech-adjacent classification tasks. O... -
Verizon and Corning Announce Multi-billion Dollar Optical Fiber Supply Agreement for Broadband Expansion and Next-Gen AI Infrastructure
GlobeNewswire USA Overview Verizon and Corning have entered a multi-year, multi-billion dollar supply agreement for over 80 million miles of high-density optical fiber and connectivity solutions, spanning 2027 to 2032. This deal supports... -
Qualcomm Unveils Snapdragon X7 Gen 2: Doubles NPU AI Processing Power for Enhanced On-Device AI in Next-Gen AI PCs and Premium Smartphones
Qualcomm Press Release USA Overview Qualcomm has officially launched its Snapdragon X7 Gen 2 platform, designed for AI PCs and premium smartphones, featuring an integrated NPU that doubles its predecessor's AI processing power. This new ... -
Cerebras Systems Achieves AI Inference Breakthrough with Wafer-Scale Engine 3: Delivering Ultra-Low Latency and High Throughput for Generative AI
Cerebras Systems Press Release USA Overview Cerebras Systems has announced a significant leap in AI inference capabilities with its Wafer-Scale Engine 3 (WSE-3), demonstrating record-breaking low latency and high throughput for large-sca... -
Edge AI Shifts to Micro-Desktops & On-Device Personal Systems: 100 Billion Parameter Models Now Run Locally
Metaplugs News International Overview The AI industry is undergoing a fundamental hardware restructuring from cloud-only inference to compact on-device systems. A new generation of NPU-equipped mini-AI desktop PCs enables local execution... -
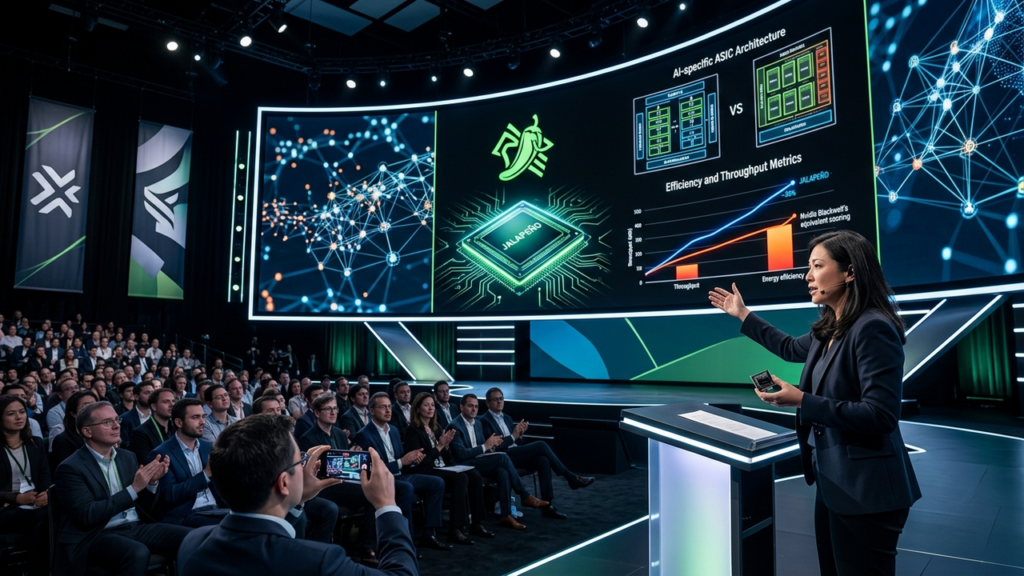
Hot Chips 2026: OpenAI Unveils ‘Jalapeño’ AI ASIC, Claiming 30% Efficiency & Throughput Gains Over Nvidia Blackwell
Tom's Hardware USA Overview At Hot Chips 2026, OpenAI unveiled 'Jalapeño,' an AI-developed custom AI ASIC, claiming up to 30% efficiency and throughput improvements over Nvidia's high-performance Blackwell GPUs. Jalapeño utilizes a NUMA-... -
Liquid AI Debuts LFM2.5-2.6B: A Powerful AI Agent Model Running on Raspberry Pi Without Cloud or GPUs
VentureBeat USA Overview AI startup Liquid AI debuted LFM2.5-2.6B, a new open-weight language model designed for agentic workloads that can run on local hardware without cloud inference or GPUs. This model enables edge AI applications on... -
SiliconFlow Launches Real-Time LLM Benchmarking Platform, Aiming for Industry Standardization
SiliconFlow International Overview SiliconFlow has unveiled a cutting-edge real-time benchmarking tool for large language models (LLMs), enabling comprehensive evaluation of inference speed, accuracy, and cost-efficiency. This platform p...